What you need
- Ruby 3.2 or newer. net/http and json are in the standard library, so there is nothing to install.
- An API key from the dashboard, in an environment variable rather than in the file.
- A free account, if you do not have one: 100 screenshots a month, no card.
Create the key on the API keys page. It is shown once, at creation, so store it before closing the dialog, and keep it on the server: a key in browser or mobile code is readable by everyone who has the app. ENV.fetch rather than ENV[] in the examples, so a missing key stops the script with a KeyError instead of sending Bearer and nothing.
The request
Save this as screenshot.rb. It asks for one page at a 1280 × 800 viewport, at twice the pixel density, as WebP, and writes what comes back to a file:
# screenshot.rb: request one screenshot and save it.
require "json"
require "net/http"

uri = URI("https://api.urlshot.io/v1/screenshot")
uri.query = URI.encode_www_form(
  url: "https://en.wikipedia.org/wiki/Cartography",
  format: "webp",
  quality: 80,
  viewport_width: 1280,
  viewport_height: 800,
  device_scale_factor: 2,
)

response = Net::HTTP.get_response(uri, "Authorization" => "Bearer #{ENV.fetch("URLSHOT_API_KEY")}")

# Anything that is not an image is the JSON error envelope.
unless response.is_a?(Net::HTTPSuccess)
  error = JSON.parse(response.body).fetch("error")
  raise "#{error["code"]}: #{error["message"]} (request #{error["requestId"]})"
end

File.binwrite("screenshot.webp", response.body)
puts "Wrote screenshot.webp"
Run it
export URLSHOT_API_KEY=sk_your_key_here
ruby screenshot.rb
One render, one credit. Net::HTTP.get_response uses HTTPS because the URI does, and waits up to 60 seconds for an answer, longer than any render the API runs.
What comes back
On success, response.body is the image itself: no JSON wrapper, no base64. File.binwrite writes it without any newline translation. This is the file that script writes:
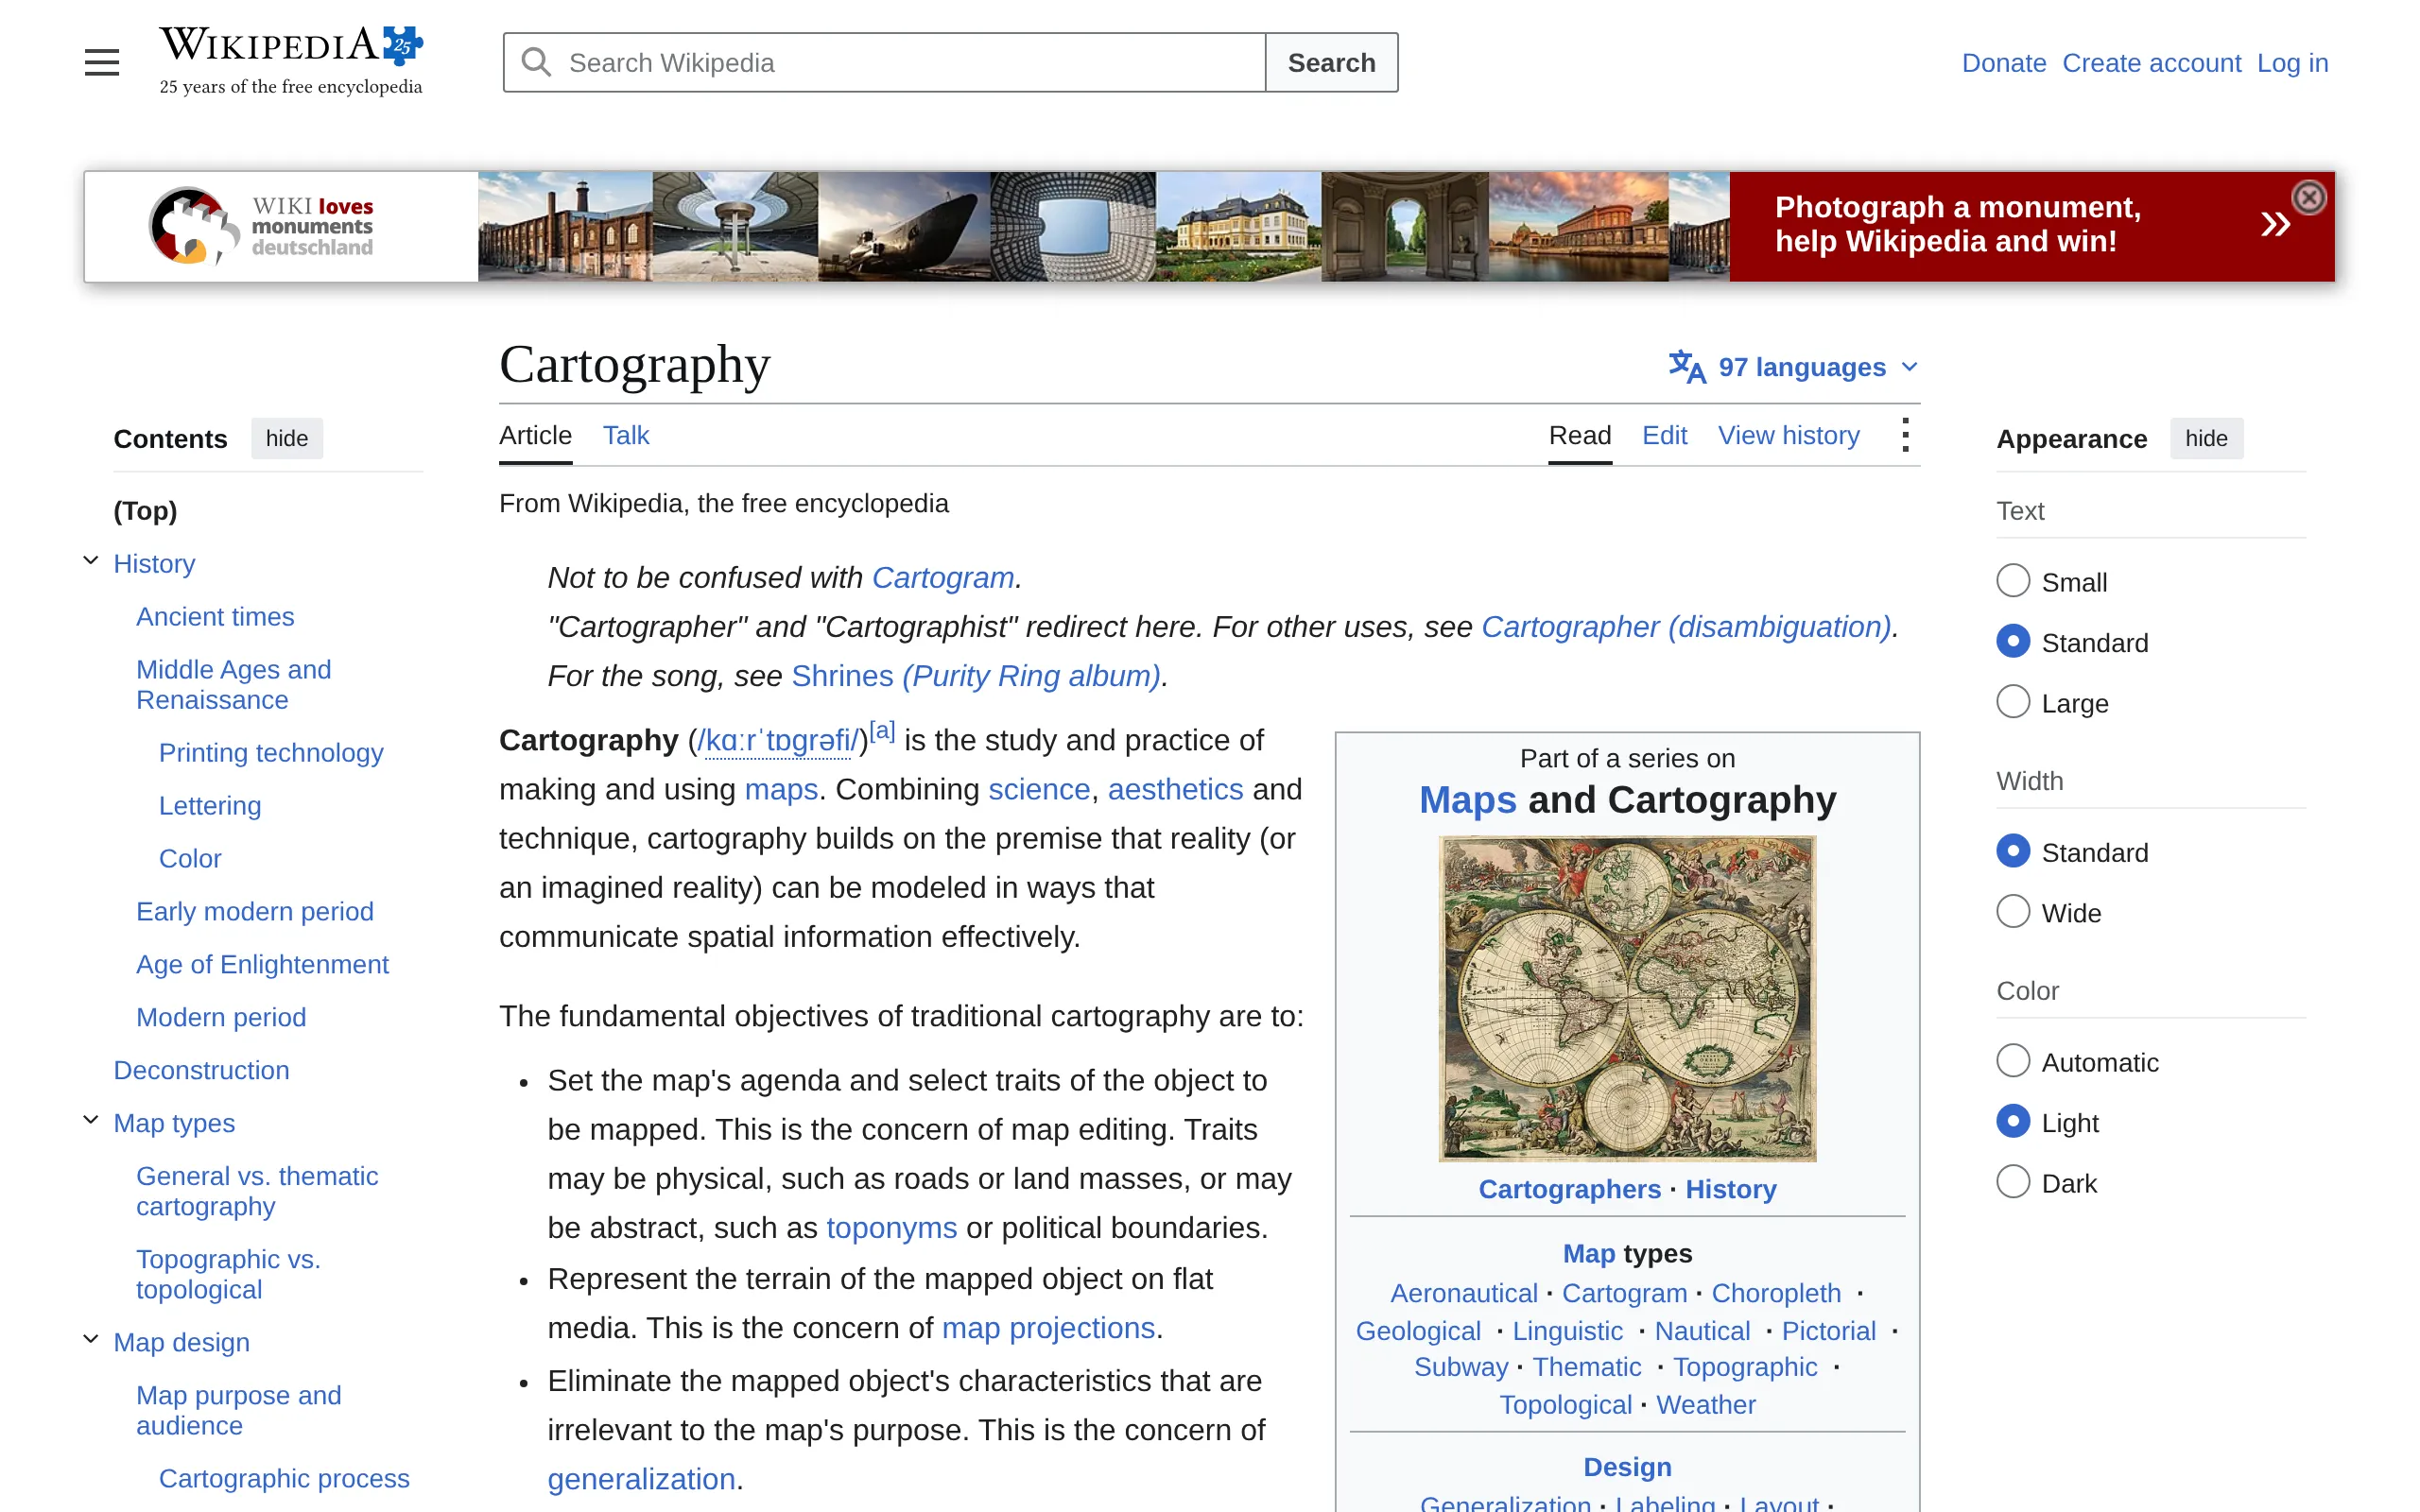
Every response also carries headers that account for the call:
| X-Request-ID | Opaque identifier for this request. Quote it in any support conversation. |
|---|---|
| X-Urlshot-Cache | HIT when the image was served from cache, MISS when it was rendered, BYPASS when cache_ttl was 0. |
| X-Urlshot-Credits-Used | Render credits consumed by this request. A cache hit consumes zero. |
| X-RateLimit-Limit | Renders your plan may run at once. |
| X-Urlshot-Renderer | The renderer build that produced the image, such as v4:4572cafff9ea; on a cache hit, the build that made the cached image. For support conversations, not for branching on. |
| X-RateLimit-Remaining | Render slots still free after this request. Absent on a cache hit, where it is unknown rather than zero. |
| Cache-Control | How long a browser may reuse the image: private, max-age=<seconds> when cache_ttl is set, and on a cache hit no longer than the cached copy has left; no-store when cache_ttl is 0. |
Read them from the response like a hash; Net::HTTP finds a header whatever the case of its name:
# After the request: what it cost, and how to refer to it.
# Net::HTTP finds a header whatever the case of its name.
credits = response["X-Urlshot-Credits-Used"] # "1", or "0" from cache
request_id = response["X-Request-ID"]
puts "request #{request_id} used #{credits} credit(s)"
Errors and retries
A failed call returns JSON instead of an image, with a stable code, a message, and the requestId to quote if you ask about it. The scripts here raise with all three.
These codes are worth retrying, and each comes with a Retry-After header in seconds:
concurrency_limit_exceeded, 429: The workspace is already running the maximum number of concurrent renders.rate_limit_exceeded, 429: The request rate limit for this API key has been exceeded.service_unavailable, 503: The screenshot service is temporarily unavailable.
Every other code fails the same way however often you send it, and one that got as far as the browser has already cost a credit. So retry on Retry-After and nothing else:
require "json"
require "net/http"

# Requests a screenshot, retrying only when the API says how long to wait.
def screenshot(params, attempts: 4)
  uri = URI("https://api.urlshot.io/v1/screenshot")
  uri.query = URI.encode_www_form(params)

  1.upto(attempts) do |attempt|
    response = Net::HTTP.get_response(uri, "Authorization" => "Bearer #{ENV.fetch("URLSHOT_API_KEY")}")
    return response.body if response.is_a?(Net::HTTPSuccess)

    # Only a 429 or 503 carries Retry-After, in seconds. Anything else fails
    # the same way however often it is sent.
    retry_after = response["Retry-After"]
    error = JSON.parse(response.body).fetch("error")
    if retry_after.nil? || attempt == attempts
      raise "#{error["code"]}: #{error["message"]} (request #{error["requestId"]})"
    end

    sleep Integer(retry_after)
  end
end

# Braces, because the method takes a hash: without them Ruby reads url: and
# format: as keyword arguments, and the call fails.
image = screenshot({
  url: "https://en.wikipedia.org/wiki/Cartography",
  format: "webp",
})
File.binwrite("screenshot.webp", image)
puts "Wrote screenshot.webp"
Integer() rather than to_i: a value that is not a number raises instead of becoming a sleep of zero. Every code is in the error reference.
More options
Every option is a query parameter with a default; add it to encode_www_form. These change a capture the most:
| full_page | Capture the full scrollable page instead of only the viewport. | boolean |
|---|---|---|
| format | Output image format. | png | jpeg | webp |
| quality | Encoder quality for jpeg and webp. Defaults to 80 for those formats and must be omitted for png. | 1–100 |
| viewport_width | Viewport width in CSS pixels. | 200–3840 |
| device_scale_factor | Device pixel ratio to emulate. | 0.5–3 |
| dark_mode | Emulate prefers-color-scheme: dark before navigation. | boolean |
| hide_selectors | CSS selector whose matching elements are hidden after navigation. Repeatable. | string[] |
| block_cookie_banners | Hide known consent dialogs and restore page scrolling before capturing. Available on every plan. | boolean |
URI.encode_www_form writes an array as the parameter repeated, which is how hide_selectors takes more than one selector, and true as the word true:
require "json"
require "net/http"

uri = URI("https://api.urlshot.io/v1/screenshot")
# A list becomes the parameter repeated, once for each selector.
uri.query = URI.encode_www_form(
  url: "https://en.wikipedia.org/wiki/Atlas",
  full_page: true,
  format: "png",
  hide_selectors: [".vector-header-container", ".mw-footer"],
)

response = Net::HTTP.get_response(uri, "Authorization" => "Bearer #{ENV.fetch("URLSHOT_API_KEY")}")

# Anything that is not an image is the JSON error envelope.
unless response.is_a?(Net::HTTPSuccess)
  error = JSON.parse(response.body).fetch("error")
  raise "#{error["code"]}: #{error["message"]} (request #{error["requestId"]})"
end

File.binwrite("atlas.png", response.body)
That is the whole Atlas article as a PNG, without Wikipedia's header and footer. All 17 options are in the parameter reference.
POST with a JSON body
The same options can go in a JSON body, which is easier once you send CSS: nothing to encode. JSON.generate writes Ruby's true and arrays as JSON's, which a body needs; the string "true" is rejected there. A POST needs a request object rather than get_response:
require "json"
require "net/http"

uri = URI("https://api.urlshot.io/v1/screenshot")
request = Net::HTTP::Post.new(uri, "Content-Type" => "application/json", "Authorization" => "Bearer #{ENV.fetch("URLSHOT_API_KEY")}")
# Ruby's true and arrays become JSON's true and arrays.
request.body = JSON.generate(
  url: "https://en.wikipedia.org/wiki/Atlas",
  full_page: true,
  format: "png",
  hide_selectors: [".vector-header-container", ".mw-footer"],
  custom_css: "#siteNotice { display: none !important }",
)

response = Net::HTTP.start(uri.host, uri.port, use_ssl: uri.scheme == "https", read_timeout: 60) do |http|
  http.request(request)
end

# Anything that is not an image is the JSON error envelope.
unless response.is_a?(Net::HTTPSuccess)
  error = JSON.parse(response.body).fetch("error")
  raise "#{error["code"]}: #{error["message"]} (request #{error["requestId"]})"
end

File.binwrite("atlas.png", response.body)
Put every option in the body: a POST that also has query parameters is rejected. The rest of the rules are under POST with a JSON body.
In a Rails app
In a Rails app, call the API from a controller and send the image on, so the key never reaches a browser:
# app/controllers/previews_controller.rb, with this in config/routes.rb:
#   get "previews/:page", to: "previews#show"
require "net/http"

class PreviewsController < ApplicationController
  # The pages this app shows previews of. Visitors pick a name, never an
  # address: a route that took any URL would render any page on your credits.
  PAGES = {
    "home" => "https://example.com",
    "atlas" => "https://en.wikipedia.org/wiki/Atlas",
  }.freeze

  def show
    url = PAGES[params[:page]]
    return head :not_found if url.nil?

    uri = URI("https://api.urlshot.io/v1/screenshot")
    uri.query = URI.encode_www_form(
      url: url,
      viewport_width: 1280,
      format: "webp",
      cache_ttl: 3600,
    )
    response = Net::HTTP.get_response(uri, "Authorization" => "Bearer #{ENV.fetch("URLSHOT_API_KEY")}")

    unless response.is_a?(Net::HTTPSuccess)
      error = JSON.parse(response.body).fetch("error")
      Rails.logger.error("#{error["code"]}: #{error["message"]} (request #{error["requestId"]})")
      return head :bad_gateway
    end

    expires_in 1.hour, public: true
    send_data response.body, type: response["Content-Type"], disposition: "inline"
  end
end- Visitors choose a name, not an address. A route that rendered whatever URL it was given would let anyone spend your credits on pages of their own.
- Repeat views are free.
cache_ttl=3600serves the same page from the API's cache for an hour at no cost, the longest the free plan allows, andexpires_inlets the browser keep it as long. See caching and credits. - A failure is logged, not passed on. The controller logs the code and request id and answers
502.
The request blocks a Puma thread for the seconds a render takes. For pages the app shows often, fetch the image in a background job and store it, and serve the stored copy.
Run bin/rails server and open /previews/home on port 3000, the Rails default.
Signed URLs
To put a capture straight into a page's <img>, sign the URL on your server instead. Anyone can load a signed URL, and changing any of its parameters breaks the signature:
require "openssl"
require "uri"

def signed_url(**options)
  query = URI.encode_www_form({ key: ENV.fetch("URLSHOT_KEY") }.merge(options))

  signature = OpenSSL::HMAC.hexdigest("SHA256", ENV.fetch("URLSHOT_SIGNING_SECRET"), query)

  "https://api.urlshot.io/v1/screenshot?#{query}&signature=#{signature}"
end

src = signed_url(url: "https://example.com", viewport_width: "1200")
URLSHOT_KEY is a publishable key (pk_…) and URLSHOT_SIGNING_SECRET its signing secret, both from the dashboard. OpenSSL::HMAC.hexdigest returns lowercase hex, which is what the API compares. A signed URL does not expire, so add a cache_ttl to any you publish; the reference explains why under signed URLs.
Where to go next
- The API reference — every parameter, response header and error code, generated from the contract the gateway validates against.
- Website thumbnails — small previews of many sites, fetched once and stored, which is the background-job pattern above.
- Pricing — what a credit costs once the free allowance runs out.