What you need
- curl, which macOS and almost every Linux distribution already include.
- A POSIX shell for the scripts: Terminal on a Mac, any Linux shell, or WSL or Git Bash on Windows.
- An API key from the dashboard, exported as an environment variable.
- A free account, if you do not have one: 100 screenshots a month, no card.
Create the key on the API keys page. The plaintext key is shown once, at creation, and cannot be retrieved afterwards. Export it in the terminal you will run the commands from, so it is not written into a script:
export URLSHOT_API_KEY=sk_your_key_hereThe commands continue their lines with \, as POSIX shells do. PowerShell continues them with a backtick instead, so run these in one of the shells above.
The request
-G turns each --data-urlencode into a query parameter, and encodes its value on the way, so an & or # in an address arrives intact. This asks for one page at a 1280 × 800 viewport, at twice the pixel density, as WebP:
curl -G "https://api.urlshot.io/v1/screenshot" \
  -H "Authorization: Bearer $URLSHOT_API_KEY" \
  --data-urlencode "url=https://en.wikipedia.org/wiki/Cartography" \
  --data-urlencode "format=webp" \
  --data-urlencode "quality=80" \
  --data-urlencode "viewport_width=1280" \
  --data-urlencode "viewport_height=800" \
  --data-urlencode "device_scale_factor=2" \
--output screenshot.webpCheck the status
--write-out "%{http_code}" prints the status once the body is written, and the script decides what that body was. Save it as screenshot.sh:
#!/bin/sh
# screenshot.sh: save a screenshot, or say why there is none.
set -eu

status=$(curl -sS -G "https://api.urlshot.io/v1/screenshot" \
  -H "Authorization: Bearer $URLSHOT_API_KEY" \
  --data-urlencode "url=https://en.wikipedia.org/wiki/Cartography" \
  --data-urlencode "format=webp" \
  --data-urlencode "quality=80" \
  --data-urlencode "viewport_width=1280" \
  --data-urlencode "viewport_height=800" \
  --data-urlencode "device_scale_factor=2" \
  --output screenshot.webp \
  --write-out "%{http_code}")

if [ "$status" != "200" ]; then
  # Not an image: the JSON error envelope, with a code and the request id.
  cat screenshot.webp >&2
  rm -f screenshot.webp
  exit 1
fi

echo "Wrote screenshot.webp"
Run it with sh screenshot.sh. It exits 1 with the error on stderr when there is no image, which is what a cron job or a CI step needs to notice that something went wrong.
What comes back
On success, the image bytes themselves — no JSON wrapper, no base64, nothing to decode. This is the file the request above writes, shown at the width this page has for it:
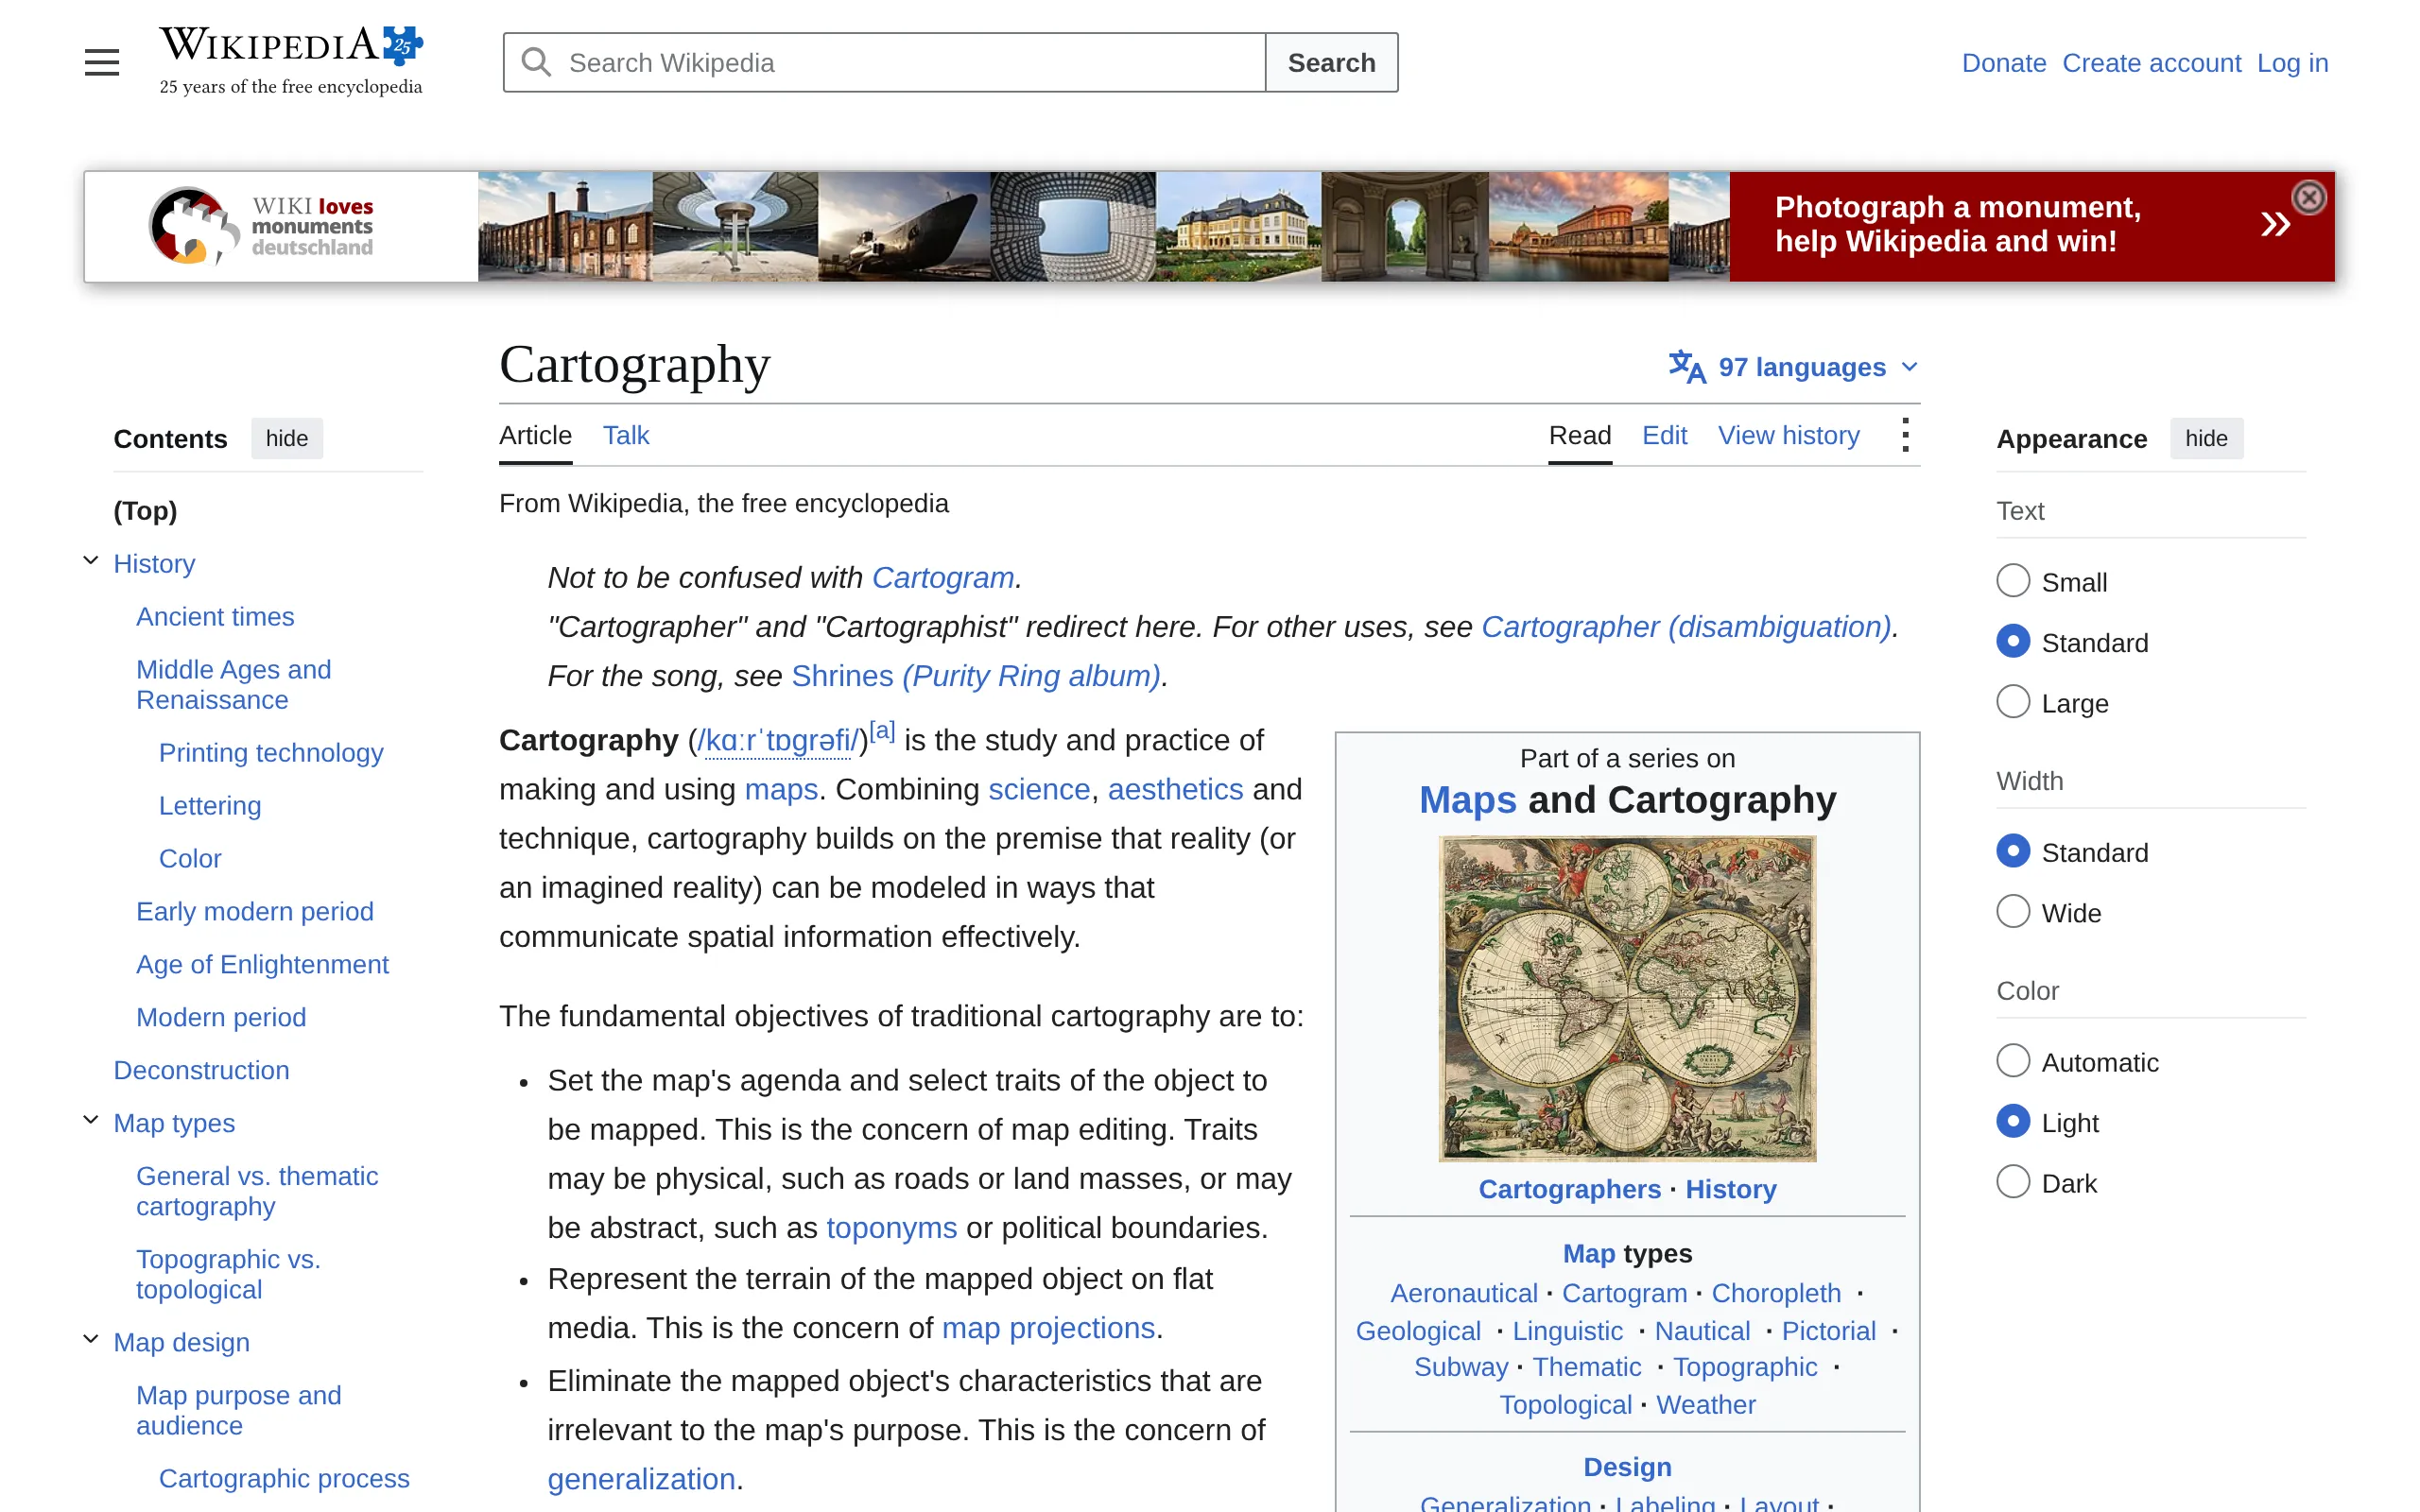
Add --dump-header - to print the response headers while the image goes to its file:
curl -sS -G "https://api.urlshot.io/v1/screenshot" \
  -H "Authorization: Bearer $URLSHOT_API_KEY" \
  --data-urlencode "url=https://en.wikipedia.org/wiki/Cartography" \
  --output screenshot.png \
  --dump-header -
They carry what you need to account for the call, on every request:
| X-Request-ID | Opaque identifier for this request. Quote it in any support conversation. |
|---|---|
| X-Urlshot-Cache | HIT when the image was served from cache, MISS when it was rendered, BYPASS when cache_ttl was 0. |
| X-Urlshot-Credits-Used | Render credits consumed by this request. A cache hit consumes zero. |
| X-RateLimit-Limit | Renders your plan may run at once. |
| X-Urlshot-Renderer | The renderer build that produced the image, such as v4:4572cafff9ea; on a cache hit, the build that made the cached image. For support conversations, not for branching on. |
| X-RateLimit-Remaining | Render slots still free after this request. Absent on a cache hit, where it is unknown rather than zero. |
| Cache-Control | How long a browser may reuse the image: private, max-age=<seconds> when cache_ttl is set, and on a cache hit no longer than the cached copy has left; no-store when cache_ttl is 0. |
Errors and retries
A failed call returns JSON instead of an image, with a stable code, a message, and the requestId to quote if you ask about it. These codes are worth retrying, and each comes with a Retry-After header in seconds:
concurrency_limit_exceeded, 429: The workspace is already running the maximum number of concurrent renders.rate_limit_exceeded, 429: The request rate limit for this API key has been exceeded.service_unavailable, 503: The screenshot service is temporarily unavailable.
Every other code fails the same way however often you send it. This script waits and tries again only when the response says how long to wait:
#!/bin/sh
# retry.sh: retry only when the API says when to.
set -eu

for attempt in 1 2 3 4; do
  status=$(curl -sS -G "https://api.urlshot.io/v1/screenshot" \
    -H "Authorization: Bearer $URLSHOT_API_KEY" \
    --data-urlencode "url=https://en.wikipedia.org/wiki/Cartography" \
    --data-urlencode "format=webp" \
    --output screenshot.webp \
    --dump-header headers.txt \
    --write-out "%{http_code}")

  if [ "$status" = "200" ]; then
    echo "Wrote screenshot.webp"
    exit 0
  fi

  # Seconds to wait, on a 429 or 503 only. Header names may arrive in lowercase.
  wait=$(sed -n 's/^[Rr]etry-[Aa]fter: *\([0-9]*\).*/\1/p' headers.txt)

  if [ -z "$wait" ] || [ "$attempt" = 4 ]; then
    # Anything else fails the same way however often it is sent.
    cat screenshot.webp >&2
    rm -f screenshot.webp
    exit 1
  fi

  sleep "$wait"
done
Not curl's own --retry. It also retries 502 and 504, which here mean the target page failed to load or render. Those requests started a browser, so each has cost a credit, and a page that failed once usually fails again. Try a higher timeout_ms first; the error reference lists every code.
More options
Every option is one more --data-urlencode, and every one has a default. These change a capture the most:
| full_page | Capture the full scrollable page instead of only the viewport. | boolean |
|---|---|---|
| format | Output image format. | png | jpeg | webp |
| quality | Encoder quality for jpeg and webp. Defaults to 80 for those formats and must be omitted for png. | 1–100 |
| viewport_width | Viewport width in CSS pixels. | 200–3840 |
| device_scale_factor | Device pixel ratio to emulate. | 0.5–3 |
| dark_mode | Emulate prefers-color-scheme: dark before navigation. | boolean |
| hide_selectors | CSS selector whose matching elements are hidden after navigation. Repeatable. | string[] |
| block_cookie_banners | Hide known consent dialogs and restore page scrolling before capturing. Available on every plan. | boolean |
To hide more than one element, give hide_selectors once for each selector. This captures the whole Atlas article as a PNG, without Wikipedia's header and footer:
curl -G "https://api.urlshot.io/v1/screenshot" \
  -H "Authorization: Bearer $URLSHOT_API_KEY" \
  --data-urlencode "url=https://en.wikipedia.org/wiki/Atlas" \
  --data-urlencode "full_page=true" \
  --data-urlencode "format=png" \
  --data-urlencode "hide_selectors=.vector-header-container" \
  --data-urlencode "hide_selectors=.mw-footer" \
  --output atlas.png
All 17 options are in the parameter reference.
POST with a JSON body
The same options can go in a JSON body instead, which is easier once you send CSS: nothing to percent-encode, and every value keeps its type. Send true, not "true", and hide_selectors as an array.
curl "https://api.urlshot.io/v1/screenshot" \
  -H "Authorization: Bearer $URLSHOT_API_KEY" \
  -H "Content-Type: application/json" \
  --data-binary @- \
  --output atlas.png <<'JSON'
{
  "url": "https://en.wikipedia.org/wiki/Atlas",
  "full_page": true,
  "format": "png",
  "hide_selectors": [
    ".vector-header-container",
    ".mw-footer"
  ],
  "custom_css": "#siteNotice { display: none !important }"
}
JSON
The quoted 'JSON' after << passes the body to curl exactly as written, with no shell quoting to escape. Put every option in the body: a POST that also has query parameters is rejected. The rest of the rules are under POST with a JSON body.
Many pages from a list
Put one address per line in urls.txt, and this takes a screenshot of each, named after its address — https://example.com becomes example-com.png:
#!/bin/sh
# capture-all.sh: one screenshot for each address in urls.txt.
set -eu

while IFS= read -r url || [ -n "$url" ]; do
  [ -z "$url" ] && continue
  name=$(printf '%s' "$url" | sed -E 's#^https?://##; s#[^A-Za-z0-9]+#-#g; s#-$##')

  status=$(curl -sS -G "https://api.urlshot.io/v1/screenshot" \
    -H "Authorization: Bearer $URLSHOT_API_KEY" \
    --data-urlencode "url=$url" \
    --data-urlencode "viewport_width=1280" \
    --output "$name.png" \
    --write-out "%{http_code}")

  if [ "$status" = "200" ]; then
    echo "$url -> $name.png"
  else
    echo "$url failed: $(cat "$name.png")" >&2
    rm -f "$name.png"
  fi
done < urls.txt- One at a time. A plan limits how many renders run at once, and a loop never has more than one.
- A failure does not stop the rest. It is reported on stderr with its code and request id, and the loop moves on.
- The last line counts.
|| [ -n "$url" ]keeps a final address that has no newline after it, whichreadwould otherwise skip.
Signed URLs
To put a capture straight into a page's <img>, sign the URL on your server instead. Anyone can load a signed URL, and changing any of its parameters breaks the signature. In a shell, openssl computes it:
#!/bin/sh
# sign.sh: print a signed screenshot URL that is safe to put in a page.
set -eu

# Percent-encode values yourself. The signature covers this exact string.
query="key=$URLSHOT_KEY&url=https%3A%2F%2Fexample.com&viewport_width=1200"

signature=$(printf '%s' "$query" \
  | openssl dgst -sha256 -hmac "$URLSHOT_SIGNING_SECRET" \
  | awk '{print $NF}')

echo "https://api.urlshot.io/v1/screenshot?$query&signature=$signature"
URLSHOT_KEY is a publishable key (pk_…) and URLSHOT_SIGNING_SECRET its signing secret, both from the dashboard. Encode each value yourself, as https%3A%2F%2F above: the signature covers the query exactly as it is sent. A signed URL does not expire, so add a cache_ttl to any you publish; the reference explains why under signed URLs.
Where to go next
- The API reference — every parameter, response header and error code, generated from the contract the gateway validates against.
- Website monitoring — the same requests on a schedule, from cron or CI, with every capture kept.
- Pricing — what a credit costs once the free allowance runs out.